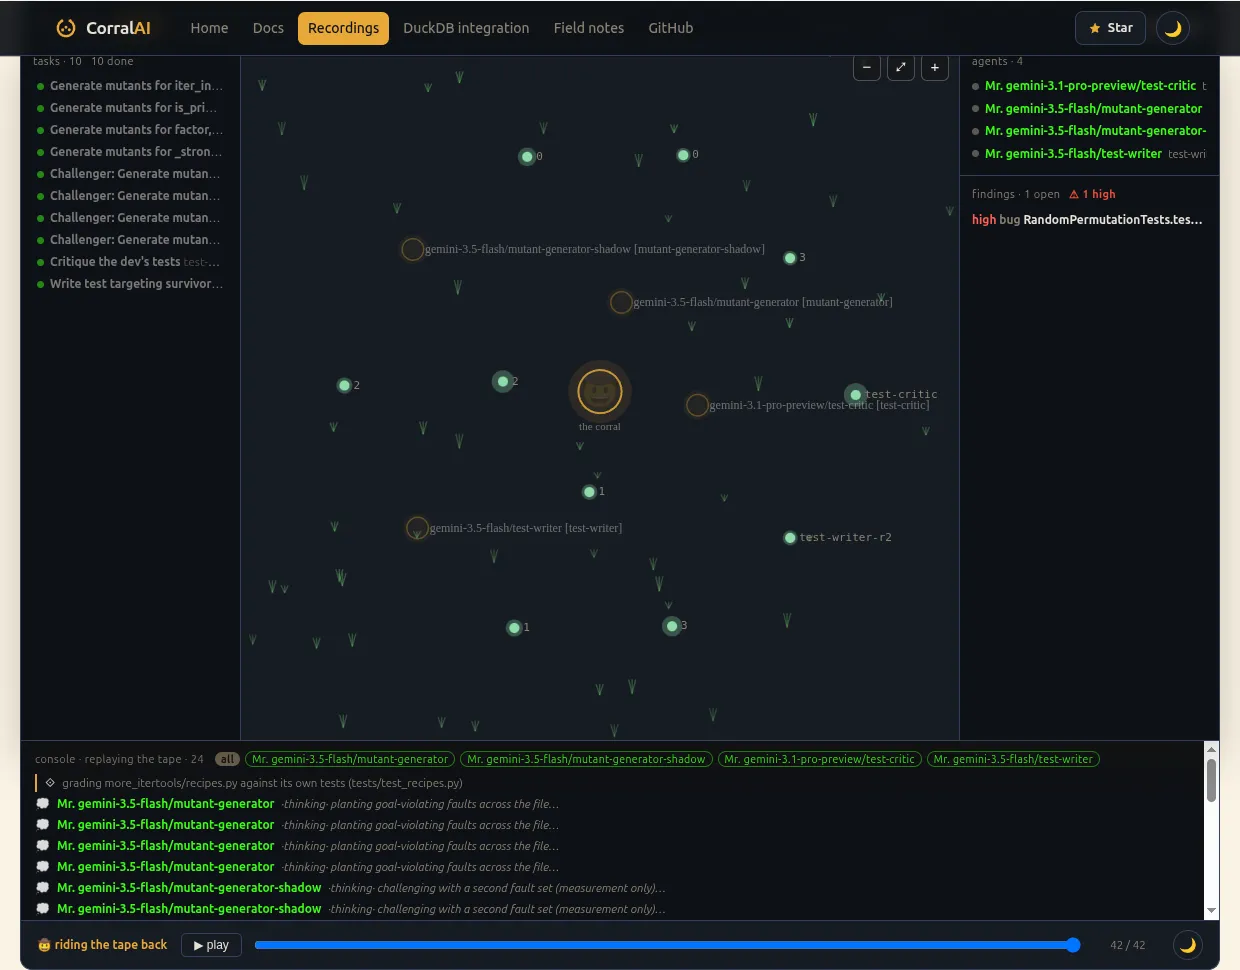
The corral (canvas view)
The corral is the default tab: every active agent in the audit herd renders as a moving node, connected by a line to each file or fault-shard it currently holds a claim on. Click any agent — on the canvas, or in the roster on the right — to filter the live console below to that agent’s lines and open its floating detail window: what it’s working on, which paths it holds, its recent activity, and the memory entries it can recall.
Anatomy of the cockpit
The corral isn’t just the canvas — it’s five regions working together, all
fed by the same /api/state snapshot:
-
Header stats (top center) — a running
N agents · N claimscount, plus a· N ⏸suffix whenever an agent is parked awaiting approval. -
Left rail — tasks — every shard in the run’s fault-generation queue, newest work first, each row showing its phase (plant, dev-run, test-write, critic-review) and (once claimed or done) the agent’s name behind a
←arrow. -
Canvas (center) — the live force-directed graph: an agent node per active audit-role seat, a path node per file or function under audit, and a line between them for every live claim. Two mutant-generator shards claiming the same function draw two lines to one path node — that’s the shard split, not a conflict.
-
Right rail — agents & findings — a roster of every active agent (labeled
model/role, e.g.gemini-3.5-flash/mutant-generator) with its most recent command line, and below it the findings panel: every open survivor — a planted mutant the dev suite hasn’t killed yet — with a⚠ N unprovencounter, since a survivor only becomes a counted, proven gap once the test-writer authors a compiling test that actually kills it. -
Bottom — live console — the real command lines the herd actually ran, newest at the bottom like a tailing log, synthesized from the run’s own events, with per-agent filter chips so you can isolate one seat’s stream:
💭 gemini-3.5-flash/mutant-generator planting goal-violating faults…
❯ gemini-3.5-flash/mutant-generator planted 5 goal-violating mutants ✓
❯ claude-sonnet-5/test-writer authored a test to close the gap
⚑ claude-haiku-4-5/test-critic flagged test_full_permutation — a dead range==tuple check
verdict: CERTIFIED — killed 18/20
The agent-detail window
Click any agent to open its floating detail window: what it’s working on, which paths it holds, its recent activity, and — at the bottom — the memory entries it can recall.
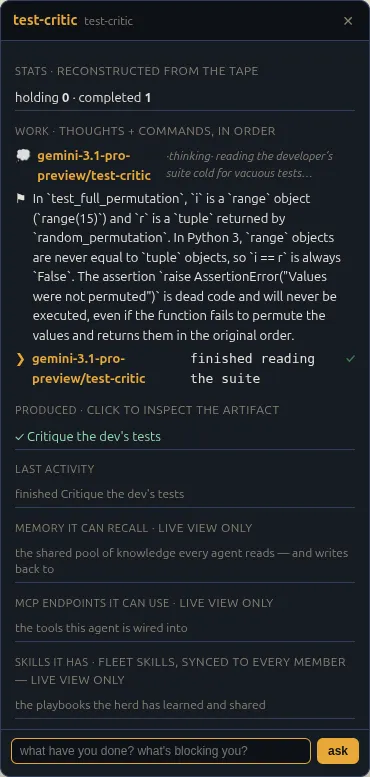
The memory-recall list above isn’t scoped to that one agent — every agent’s
window fetches it from the same call
(s.mem.List(...) inside agentDetail in internal/ui/ui.go) that backs
the Memory tab, capped at 8 entries and filtered only by the viewer’s own
visibility (private vs. shared). So an agent can only ever recall what the
brain’s own memory store actually holds — the shared corpus of
execution-verified audit findings — never more than what the person looking
at the window is themselves allowed to see.
Matrix skin
The header’s skin selector (#skinsel, defined by the SKINS table in
internal/ui/web/replay-player.js) re-voices the same live audit run in a
different vocabulary. Switching to matrix renames the corral to “the
construct” and its tabs (proposals → anomalies, completed → archive),
prefixes every agent’s displayed name with “Mr. “, swaps the ranch/grass
background for falling green glyphs (renderBg’s rain case, drawn by
drawRain), and reworks each role’s in-character chatter lines
(ROLE_LINES.matrix) into construct-flavored quips. None of that touches the
underlying run: setSkin() only rewrites DOM text and re-renders the canvas
background — the same shards, claims, survivors, and live-console lines are
still there underneath, just relabeled.